Two failures recur across enterprise AI deployments, independent of vendor, model or industry. Both look fine until the moment they don’t, and neither can be fixed by adding a policy document.
Key points
- When a document is copied from its source system into a retrieval index, the permissions that governed it do not travel with it. Most implementations quietly assume they do.
- The fix is to check permissions live at query time against the source system, not to replicate the source’s permission model inside the AI system.
- A completed governance checklist and a system ready for a live pilot are two separate claims. Treating the first as proof of the second is a category error.
- Both problems are architectural. They have to be fixed in how the system is built.
The permission problem, plainly stated
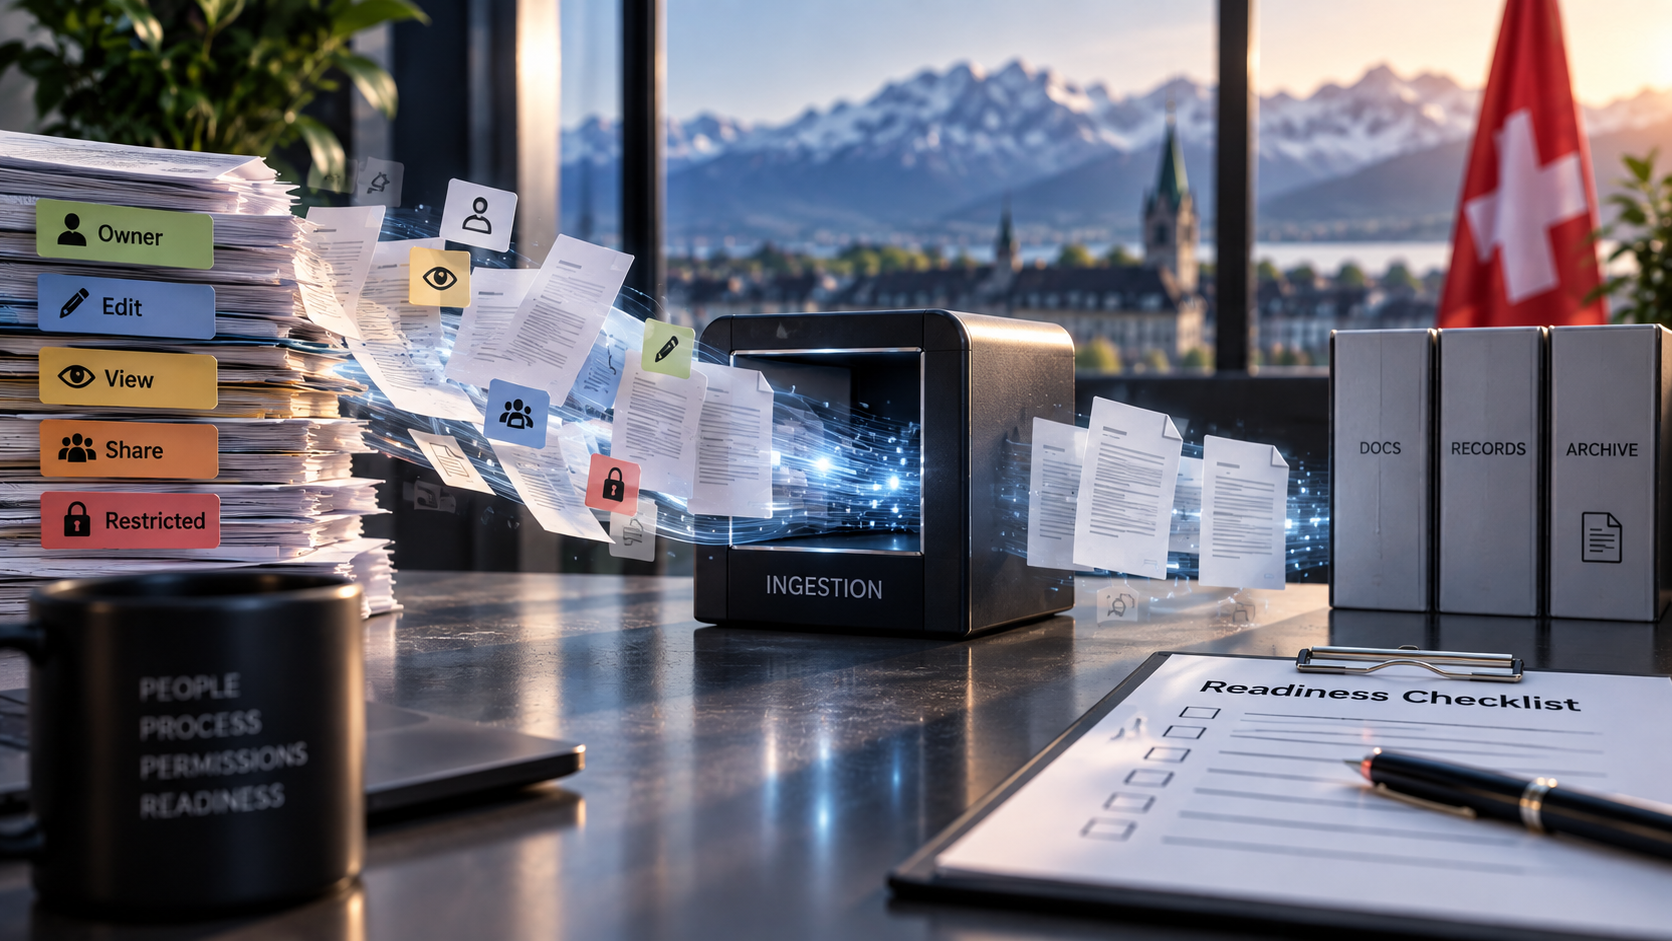
Most enterprise AI assistants built on retrieval-augmented generation work by ingesting an organisation’s documents — SharePoint, a file server, a CRM export — into a searchable index, then letting a language model answer questions from whatever the search retrieves. This is the standard pattern, and for good reason: it lets a model answer from the organisation’s actual content rather than only from its general training.
The problem is what happens to access control during ingestion. A document in SharePoint is visible only to the people and groups granted access to it. Once copied into a vector index, the index typically has no concept of who was allowed to see the original. Unless someone has deliberately engineered otherwise, every user of the AI system can potentially retrieve every ingested document, regardless of whether they could ever have opened it in the source system.
This is easy to miss because nothing about it looks broken. The system answers correctly, retrieval works, the demo goes well. The gap becomes visible only when someone asks the assistant something they were never supposed to be able to see the answer to, and it answers anyway.
Why the obvious fix doesn’t work
The instinctive response is to replicate the source system’s permission structure inside the AI system at ingestion time: tag each chunk with the access groups it belonged to, and filter retrieval by the querying user’s membership. This looks correct and is worse than it looks, for a simple reason. Permissions in the source system are not static.
Someone’s access is revoked, a document is reclassified, a group membership changes. Every one of those changes now has to be separately propagated into the AI system’s copy, or the copy silently drifts out of sync with reality. A user who lost SharePoint access last week keeps retrieving that content through the AI system indefinitely, because the permission snapshot was taken before the change.
The more defensible architecture is not to copy permissions at all. Resolve them live, at query time, by checking the querying user’s actual current access against the source system, using their own delegated credentials rather than a broad service account. This is more work to build and adds a lookup to every query. In exchange, access control is never more than one query cycle behind the source of truth, because it is not a copy. It is a live check.
The checklist problem
Separately, and just as common: organisations building an AI governance framework produce a checklist — access control, audit logging, data retention, breach response — work through it, mark every item complete, and treat the completed checklist as the signal that the system is ready to put in front of real users.
Those are two different claims. A governance checklist establishes that the known compliance and control obligations have been addressed. Whether the system is ready for a live pilot — whether it behaves correctly under real usage, whether the people operating it know what to do when something goes wrong, whether the failure modes that only appear under load have been found — is a separate operational question that a compliance checklist was never designed to answer.
Conflating the two produces a specific and avoidable failure: an organisation fully compliant on paper, launching to real users, and immediately discovering operational problems the checklist had no mechanism to catch, because catching them was never its job.
Why this matters beyond any one deployment
Neither of these is a one-off implementation bug. They are structural properties of how retrieval systems and governance programmes are typically built, which means they recur across organisations building broadly similar systems, independent of vendor, model choice or industry.
An organisation evaluating a vendor’s enterprise AI proposal, or building one internally, can ask two direct questions that surface both issues immediately. How does retrieval enforce the permissions the source system already has? And what specifically, beyond the compliance checklist, establishes that this system is ready for real users?
A vague answer to either is itself informative.
This piece describes patterns that recur across enterprise retrieval deployments generally, not the specifics of any one system. It is updated as clearer findings emerge from ongoing work in this area.